ntryk
How to Estimate Your Monthly GPU Bill Before You Deploy#
Deploying an AI application, machine learning model, or GPU-powered service requires more than choosing the right hardware. You also need to understand how much that infrastructure will cost to operate every month.
GPU cloud hosting makes powerful computing resources accessible without purchasing expensive physical hardware. However, your monthly bill can vary significantly depending on the GPU model, memory requirements, active computing hours, application traffic, and additional infrastructure resources.
For developers and businesses, estimating GPU costs before deployment is essential for creating a realistic budget, selecting suitable hardware, and avoiding unnecessary expenses.
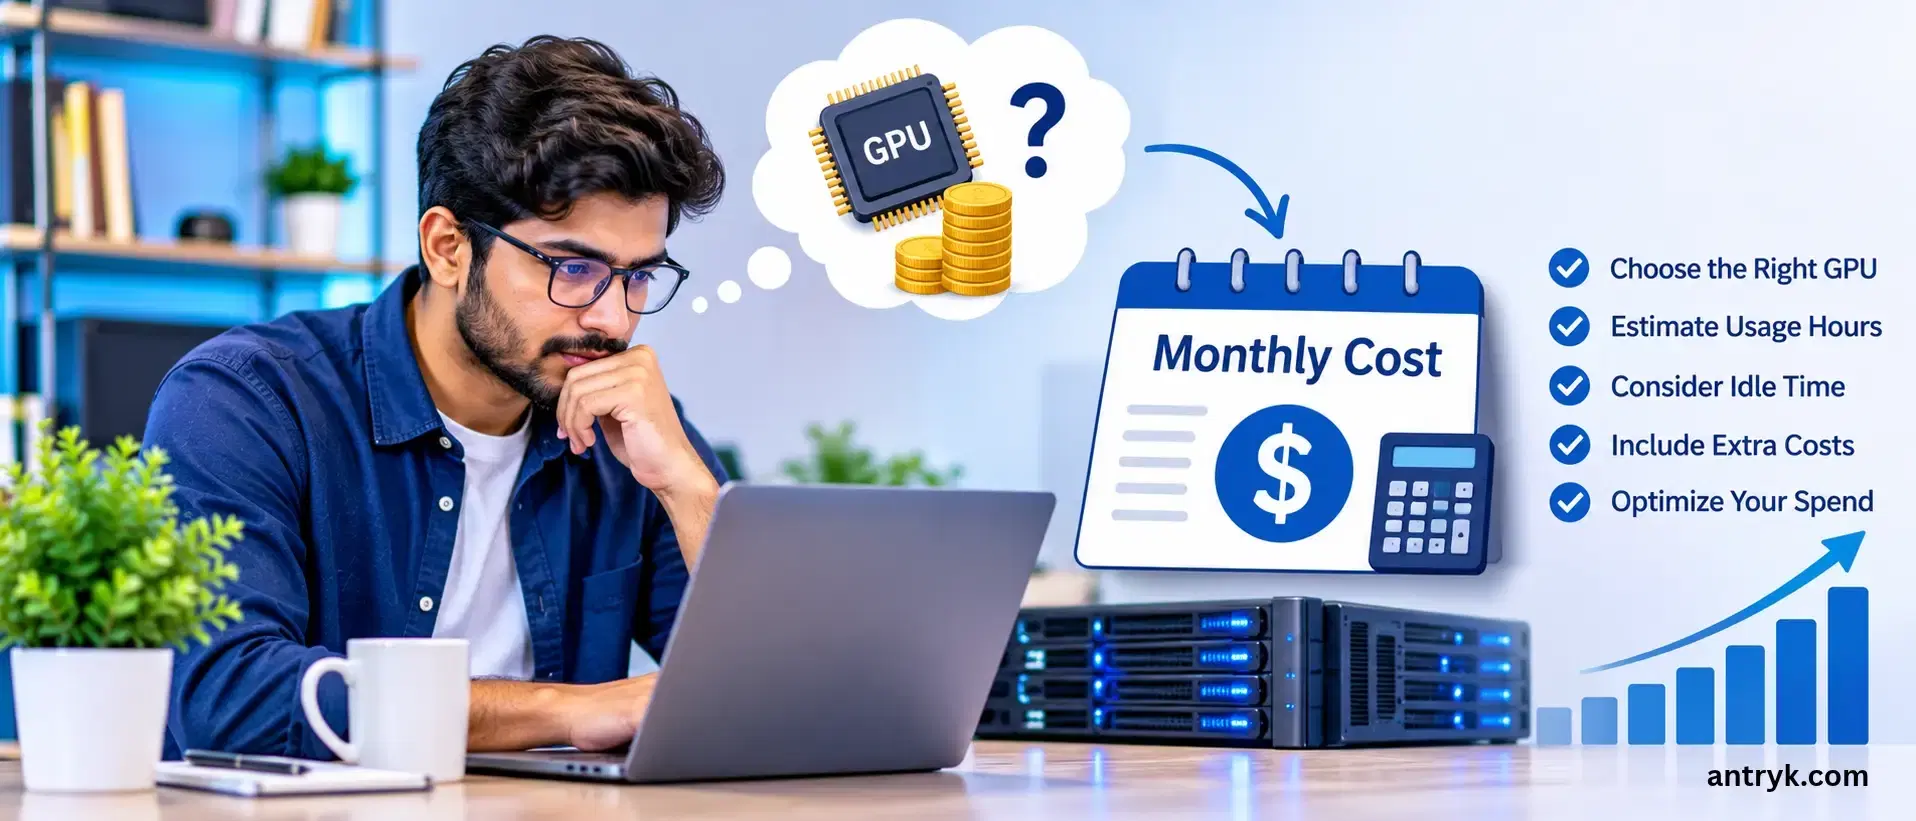
The good news is that estimating your monthly GPU bill does not have to be complicated. By understanding hourly pricing, calculating expected usage, and accounting for idle time, you can build a reasonable monthly cost estimate before launching your application.
In this guide, we explain how to estimate your monthly GPU bill before deployment, compare different GPU configurations, calculate sample workloads, and identify practical ways to reduce hosting expenses.
We will also explore how Antryk's GPU Application Service helps developers deploy GPU-powered applications with transparent hourly pricing, automated provisioning, and on-demand GPU hibernation.
Why Should You Estimate Your Monthly GPU Costs Before Deployment?#
GPU resources are essential for applications that perform computationally intensive tasks. These include artificial intelligence inference, deep learning, model training, fine-tuning, image generation, video processing, and large language model applications.
However, not every application requires the same amount of GPU computing power.
A small image classification application may operate efficiently on an entry-level GPU, while an application serving large language models may require significantly more GPU memory and processing capability.
Choosing expensive hardware without understanding your workload can increase monthly infrastructure expenses unnecessarily. On the other hand, selecting an underpowered GPU may result in slow inference, insufficient memory, and poor application performance.
Estimating your monthly GPU bill helps you:
Select hardware that matches your actual application requirements.
Calculate expected computing expenses before deployment.
Compare different GPU hosting plans.
Understand the financial impact of running applications continuously.
Identify unnecessary GPU usage and idle time.
Prepare a realistic budget for development and production.
Scale infrastructure without unexpected cost increases.
For startups, developers, and businesses operating AI applications, cost estimation should be part of the deployment planning process.
What Factors Determine Your Monthly GPU Bill?#
Before calculating your monthly GPU hosting cost, understand the factors that influence the final amount.
1. GPU Model and Memory Requirements#
The GPU model is one of the most important factors affecting your hosting expenses.
Different GPUs provide different levels of computing performance, memory capacity, and processing capabilities. More powerful GPUs generally cost more per hour.
For example:
Entry-level GPUs are suitable for lightweight inference and smaller workloads.
Mid-range GPUs can support larger AI models and generative AI applications.
High-performance GPUs are designed for demanding model training, fine-tuning, and large-scale inference.
GPU memory, commonly measured in gigabytes (GB), is equally important. If your model requires more memory than the selected GPU provides, you may encounter out-of-memory errors or performance limitations.
Therefore, choose a GPU based on both processing requirements and memory consumption.
2. Number of Active GPU Hours#
Most GPU cloud platforms calculate computing expenses based on usage time.
If your GPU instance runs for 10 hours per day, your monthly bill will generally be lower than an instance running continuously for 24 hours per day.
For a simple estimate:
Monthly GPU hours = Daily active hours × Number of operating days
For example, an application using a GPU for 6 hours per day over 30 days consumes:
6 × 30 = 180 GPU hours.
This is the foundation of your monthly GPU cost calculation.
3. Application Traffic and Workload#
Your application's workload determines how frequently GPU resources are required.
Consider two examples:
Application A: Internal AI development tool
A development team uses an AI model for testing and experimentation during working hours. The GPU is active for approximately 5–7 hours per day.
Application B: Customer-facing AI application
An AI chatbot receives requests throughout the day and needs GPU resources available to serve users.
Although both applications use GPUs, their usage patterns are different.
Understanding your expected traffic helps you estimate whether you need occasional GPU computing, scheduled availability, or continuous production capacity.
4. CPU, RAM, and Supporting Infrastructure#
GPU performance does not operate independently of the rest of your infrastructure.
Your application may also require CPU resources, system memory, persistent storage, and networking.
For example, an AI inference application may need:
CPU resources for application logic.
RAM for loading data and managing application processes.
GPU memory for model execution.
Storage for model files and application data.
Networking for receiving requests and returning results.
Review which resources are included in your selected plan and which may generate additional charges.
5. Idle GPU Time#
Idle time is another important factor when estimating your monthly GPU bill.
An application may not process requests continuously, but its GPU instance may remain active.
For example, a development application might be used for only three hours each day while its GPU instance remains running for the entire day.
If your provider bills for active GPU runtime, unnecessary operating hours can increase your expenses.
This is why features such as GPU hibernation can be useful for intermittent workloads.
Step 1: Choose the Right GPU for Your Application#
The first step in estimating your monthly GPU bill is selecting suitable hardware.
Do not automatically choose the most powerful GPU available. Instead, evaluate your application's model size, memory consumption, processing requirements, and expected workload.
GPU Requirements for AI Inference#
AI inference involves using an already-trained model to generate predictions, classifications, responses, or other outputs.
Examples include:
AI chatbots.
Image recognition applications.
Recommendation systems.
Document processing tools.
Natural language processing applications.
Image generation services.
Smaller inference workloads may operate efficiently on entry-level GPUs. Applications processing larger models or handling higher request volumes may require more powerful hardware.
GPU Requirements for Model Training and Fine-Tuning#
Model training and fine-tuning generally require more computing resources than lightweight inference.
The required GPU depends on:
Model architecture and parameter count.
Dataset size.
Batch size.
Training precision.
Memory requirements.
Training duration.
A small machine learning experiment may work on a lower-cost GPU, whereas large deep learning workloads may require enterprise-class hardware.
How GPU Memory Affects Your Monthly Budget#
GPU memory, or VRAM, determines how much model data and related computation can fit on the GPU.
If your model exceeds available VRAM, you may need techniques such as quantization, model offloading, or smaller batch sizes. Alternatively, you may need a GPU with greater memory capacity.
Before selecting a plan, estimate the memory required by your model and test its performance.
The objective is to find the lowest-cost GPU that reliably handles your workload.
Step 2: Calculate Your Expected Monthly GPU Usage#
After selecting a suitable GPU category, estimate how many hours your application will use it.
Your usage estimate should reflect real operating patterns rather than assuming that every application runs continuously.
Estimate Daily GPU Runtime#
Start by determining how many hours your GPU will be active each day.
Consider these examples:
| Application type | Estimated daily GPU usage |
|---|---|
| Development and testing | 3 hours |
| Small AI application | 5 hours |
| Regular inference workload | 8 hours |
| Production application | 12 hours |
| Always-on AI service | 24 hours |
These are illustrative planning scenarios, not industry benchmarks. Your actual usage will depend on application traffic and operating requirements.
Calculate Monthly GPU Hours#
Use the following formula:
Monthly GPU Hours = Daily GPU Hours × Operating Days
For example, suppose your application uses a GPU for 8 hours per day and operates for 30 days.
8 × 30 = 240 GPU hours.
Your estimated monthly usage is 240 hours.
If you operate multiple GPU instances simultaneously, calculate their usage separately and add the costs together.
Account for Development, Testing, and Production Usage#
Your GPU usage may change throughout the application lifecycle.
For example:
Development: Running experiments and testing models.
Staging: Validating deployment configurations.
Production: Processing real customer requests.
Maintenance: Testing updates and troubleshooting issues.
Include these activities in your monthly estimate. Otherwise, your actual bill may be higher than your original budget.
Step 3: Calculate Your Monthly GPU Compute Cost#
Once you know your selected GPU and expected usage hours, you can estimate the monthly computing expense.
The basic formula is:
Monthly GPU Compute Cost = Hourly GPU Rate × Monthly Active GPU Hours
For example, if your GPU costs $0.55 per hour and operates for 200 hours:
$0.55 × 200 = $110.
Your estimated GPU compute cost is $110 per month.
Antryk GPU Application Service Pricing#
Antryk provides multiple GPU configurations for different AI and machine learning workloads.
The following rates are displayed on its GPU Application Service pricing page:
| GPU configuration | GPU memory | Hourly price |
|---|---|---|
| RTX 4000 | 16 GB | $0.18/hour |
| RTX 6000 | 48 GB | $0.55/hour |
| L40 | 48 GB | $1.10/hour |
| A100 | 80 GB | $1.37/hour |
| H100 PRO | 80 GB | $2.45/hour |
These rates are listed in USD and may change. Confirm the current pricing and configuration details on the Antryk GPU Application Service pricing page before deploying.
Example 1: Using a GPU for 100 Hours Per Month#
Suppose you are developing a lightweight AI application and select the RTX 4000 configuration.
Hourly price: $0.18
Monthly active hours: 100
Calculation:
$0.18 × 100 = $18.
Your estimated monthly GPU compute cost is $18.
This arrangement may be useful for developers who need GPU resources for occasional testing, experimentation, or lightweight inference.
Example 2: Using a GPU for 200 Hours Per Month#
Suppose your application requires a higher-memory GPU and you choose the RTX 6000 configuration.
Hourly price: $0.55
Monthly active hours: 200
Calculation:
$0.55 × 200 = $110.
Your estimated monthly GPU compute cost is $110.
This scenario illustrates how a mid-range GPU configuration can support a workload that needs more memory while maintaining a usage-based cost structure.
Example 3: Running a GPU Application 24/7#
Now consider an application that needs continuous GPU availability.
Assume the GPU operates for 24 hours per day over a 30-day month.
Monthly GPU hours:
24 × 30 = 720 hours.
If you select the A100 configuration at $1.37 per hour:
$1.37 × 720 = $986.40.
Your estimated monthly GPU compute cost is $986.40.
This example shows why continuous GPU operation requires careful budgeting, particularly for production applications.
Compare Estimated Monthly Costs Across GPU Models#
The following table compares estimated compute expenses using Antryk's displayed hourly rates.
| GPU configuration | 100 hours | 200 hours | 730 hours |
|---|---|---|---|
| RTX 4000 | $18 | $36 | $131.40 |
| RTX 6000 | $55 | $110 | $401.50 |
| L40 | $110 | $220 | $803 |
| A100 | $137 | $274 | $1,000.10 |
| H100 PRO | $245 | $490 | $1,788.50 |
The 730-hour column represents an approximate 24/7 month using a 730-hour budgeting assumption.
These figures represent GPU compute charges only. They do not automatically include any separately billed storage, networking, taxes, or other services.
The comparison demonstrates how choosing a GPU based on actual workload requirements can significantly influence your monthly infrastructure budget.
Step 4: Include Idle Time and GPU Hibernation in Your Estimate#
One of the most overlooked aspects of GPU cloud pricing is the cost of keeping resources active when they are not being used.
Imagine that you develop an AI application that requires GPU processing for only four hours per day.
If your GPU remains active for 24 hours, you may pay for substantially more computing time than your application needs.
What Happens When Your GPU Is Running but Not Processing Requests?#
An active GPU instance may continue consuming billable runtime even when it is not processing meaningful workloads.
Common situations include:
Development environments left running overnight.
Applications with unpredictable traffic.
AI experiments completed before the GPU is stopped.
Testing environments that are used only occasionally.
Production workloads with extended periods of low activity.
Monitoring active runtime is important because unused computing capacity can increase your monthly bill.
How GPU Hibernation Can Reduce Idle Costs#
GPU hibernation allows a supported GPU service to pause its active computing workload when it is not needed.
Instead of paying the full active GPU rate throughout an idle period, you may incur a much lower standby charge, depending on the provider's billing policy.
Antryk offers on-demand GPU hibernation, allowing developers to pause GPU compute after use and reduce idle-time expenses.
For example, consider a developer who uses an RTX 4000 for four hours each day.
Without hibernation:
24 × 30 = 720 active hours.
Estimated cost:
720 × $0.18 = $129.60.
With hibernation after four hours of daily use:
4 × 30 = 120 active hours.
Estimated active compute cost:
120 × $0.18 = $21.60.
This represents a potential active compute saving of $108 per month before considering any standby charges or other billing conditions.
Important: This comparison assumes that the GPU is billed at the displayed hourly rate while active. It excludes standby charges, startup time, and any other applicable fees. Check the provider's current hibernation and billing rules before using the estimate.
When Should You Hibernate Your GPU Instance?#
GPU hibernation can be particularly useful when:
You run development and testing environments.
Your AI application receives requests only during certain hours.
You perform scheduled model training.
Your GPU workload operates intermittently.
You do not need continuous GPU availability.
However, hibernation may not be appropriate for every application. Services that require uninterrupted availability or immediate response times need careful planning.
Step 5: Account for Additional Infrastructure Costs#
Your GPU hourly rate is an important part of the budget, but it may not represent every expense associated with deploying an application.
Before finalizing your monthly estimate, review the following resources.
Persistent Storage and Application Data#
AI applications often require storage for:
Model weights and checkpoints.
Datasets.
Application files.
Logs and generated outputs.
Temporary processing files.
Check whether persistent storage is included in your plan or billed separately.
CPU and RAM Requirements#
Your application may need CPU and RAM resources for preprocessing, API requests, data loading, and background tasks.
Insufficient CPU or memory can create bottlenecks even when the GPU is powerful enough.
Review the specifications of your chosen GPU plan and determine whether they meet your application's requirements.
Networking and Data Transfer Fees#
Applications that process large datasets or serve media-heavy requests may transfer significant amounts of data.
Check whether your provider applies separate charges for bandwidth, outbound traffic, or other networking resources.
Deployment and Infrastructure Management Costs#
Some cloud platforms charge separately for deployment pipelines, orchestration, build processes, or environment management.
Antryk states that Git integration, build configuration, environment variable management, and infrastructure provisioning are included in its GPU service plans rather than charged as separate deployment pipeline fees.
This can make it easier to understand the infrastructure cost associated with deploying your application.
Nevertheless, always review the complete pricing terms to identify any separately billed resources.
Step 6: Estimate GPU Costs for Different Application Types#
Your monthly GPU bill will depend on the type of application you deploy.
Here are some examples to help you understand how different workloads affect infrastructure planning.
Monthly GPU Budget for a Small AI Startup#
A small startup may use an AI model for development, internal testing, and limited customer requests.
Suppose the startup uses an RTX 4000 for 120 active hours per month.
Calculation:
120 × $0.18 = $21.60.
Estimated GPU compute expense: $21.60 per month.
This is an illustrative starting point for a small workload. The startup should also consider storage, application hosting, and potential increases in usage as the product grows.
Monthly GPU Budget for an AI Inference Application#
An inference application may process requests during business hours.
Assume the application uses an RTX 6000 for 8 hours per day over 30 days.
Monthly usage:
8 × 30 = 240 hours.
Estimated cost:
240 × $0.55 = $132.
Estimated GPU compute expense: $132 per month.
If the application receives unpredictable traffic, the developer should monitor actual usage and evaluate whether hibernation or a different operating arrangement is appropriate.
Monthly GPU Budget for an Image Generation Application#
An image generation application may require GPU resources for processing image requests.
Suppose it uses an L40 GPU for 200 hours per month.
Calculation:
200 × $1.10 = $220.
Estimated GPU compute expense: $220 per month.
Actual requirements will depend on the image generation model, resolution, batch size, request volume, and processing performance.
Monthly GPU Budget for an LLM-Based Application#
Large language model applications may need GPUs with greater memory capacity.
For example, assume an application uses an H100 PRO configuration for 150 active hours per month.
Calculation:
150 × $2.45 = $367.50.
Estimated GPU compute expense: $367.50 per month.
This is an example rather than a recommendation that every LLM application needs an H100. Smaller models, quantization, optimized inference engines, or other configurations may reduce hardware requirements.
Step 7: How to Reduce Your Monthly GPU Bill Before Deployment#
Estimating costs is only the first step. You should also identify opportunities to reduce expenses without compromising application performance.
1. Select a GPU Based on Actual Workload Requirements#
Do not choose a GPU solely because it has the highest specifications.
Start with your model's memory and processing requirements. Test different configurations and compare their performance.
A less expensive GPU may be sufficient for your application.
2. Optimize Model Size and Inference Performance#
Model optimization can help reduce the computing resources needed to serve requests.
Consider techniques such as:
Model quantization.
Efficient inference frameworks.
Appropriate batch sizing.
Model pruning, where suitable.
Caching repeated results.
Reducing unnecessary model execution.
The best optimization strategy depends on your model and application requirements.
3. Avoid Leaving GPU Instances Running Unnecessarily#
Review your development and testing environments regularly.
Stop GPU instances when experiments are complete and schedule workloads whenever possible.
Small changes to daily operating habits can reduce unnecessary active GPU hours.
4. Use GPU Hibernation for Intermittent Workloads#
If your application does not require continuous GPU processing, use an available hibernation feature to reduce idle compute expenses.
Check how the service handles standby charges, resuming workloads, persistent storage, and application availability before relying on this approach.
5. Monitor Usage and Review Your Budget#
Track active GPU hours, application traffic, and resource consumption.
Compare your estimated monthly budget with actual usage and adjust your configuration when necessary.
For production applications, establish a monthly spending target and review infrastructure costs regularly.
6. Upgrade GPU Resources Only When Necessary#
Your application may begin with a relatively small workload and grow over time.
Rather than paying for enterprise hardware from the beginning, start with a configuration that meets your current requirements.
Upgrade when model size, traffic, or performance demands justify the additional expense.
How Antryk GPU Application Service Helps You Manage GPU Costs#
Choosing the right GPU hosting platform can simplify deployment and make infrastructure budgeting more predictable.
Antryk's GPU Application Service provides dedicated NVIDIA GPU configurations for AI inference, model training, fine-tuning, and other GPU-accelerated applications.
Pay-Per-Use Hourly GPU Pricing#
Antryk displays hourly pricing for different GPU configurations, helping developers estimate computing expenses based on expected active runtime.
Instead of relying on a single hardware configuration for every workload, you can evaluate available options and select one that matches your application's requirements.
Multiple GPU Configurations for Different Workloads#
Antryk offers GPU configurations including RTX 4000, RTX 6000, L40, A100, and H100 PRO.
This range allows developers to compare hardware options for lightweight inference, generative AI, and more demanding workloads.
GPU Hibernation to Reduce Idle Costs#
Antryk supports on-demand GPU hibernation, allowing developers to pause compute when it is not required.
This can be useful for development environments, scheduled workloads, and applications with intermittent processing requirements.
Review the current standby billing conditions to estimate the complete cost.
Git-Based Deployment and Docker Support#
Antryk supports Git-based deployments and containerized workloads.
Developers can connect a repository, configure installation and runtime commands, manage environment variables, and deploy applications on dedicated GPU infrastructure.
This helps simplify the process of moving an AI application from development to deployment.
Automated Infrastructure Provisioning#
Antryk includes automated infrastructure provisioning as part of its GPU service plans.
The platform handles repository retrieval, dependency installation, build configuration, GPU provisioning, and application startup.
According to its pricing page, these deployment pipeline features are included rather than billed as separate orchestration charges.
Flexible GPU Plan Upgrades#
Your computing requirements may increase as your application develops.
Antryk allows developers to upgrade GPU plans and redeploy without rebuilding the deployment configuration from scratch.
This can help businesses begin with a smaller configuration and expand their resources as their workload grows.
Ready to estimate your GPU hosting expenses? Explore Antryk GPU Application Service pricing to compare available GPU configurations and choose a suitable option for your application.
Monthly GPU Cost Estimation Checklist#
Before deploying your application, use this checklist to review the important cost factors.
| Cost estimation factor | What to check |
|---|---|
| GPU model | Does it meet your workload requirements? |
| GPU memory | Is there sufficient VRAM for your model? |
| Hourly pricing | What is the current hourly rate? |
| Active usage | How many GPU hours will you need monthly? |
| Idle time | Can unused compute be paused? |
| CPU and RAM | Are supporting resources sufficient? |
| Storage | Are persistent storage costs included? |
| Networking | Are there additional data transfer charges? |
| Deployment | Are build and provisioning fees included? |
| Scaling | How will costs change as traffic increases? |
Completing this checklist before deployment can help you create a more realistic infrastructure budget.
Frequently Asked Questions About Monthly GPU Costs#
1. How do I estimate my monthly GPU bill?#
Multiply the GPU's hourly rate by the expected number of active computing hours per month.
For example, a GPU costing $0.55 per hour and running for 200 hours will generate an estimated compute cost of $110.
Add any applicable storage, networking, standby, and other infrastructure charges to estimate your total bill.
2. How much does it cost to run a GPU server for a month?#
The cost depends on the GPU model and operating hours.
Using Antryk's displayed pricing, an RTX 4000 costs $0.18 per active hour, while an H100 PRO costs $2.45 per active hour.
At 730 hours per month, the estimated GPU compute costs are $131.40 and $1,788.50, respectively. These figures exclude any additional charges.
3. Is GPU cloud hosting cheaper than buying a GPU?#
GPU cloud hosting can be more economical for short-term projects, experimentation, and workloads that do not require continuous computing.
Buying physical hardware may be worth evaluating for predictable, sustained workloads, but it also involves upfront hardware expenses, electricity, maintenance, cooling, and infrastructure management.
The better option depends on utilization, ownership costs, and operational requirements.
4. Do I pay for GPU resources when my application is idle?#
It depends on your hosting provider's billing model.
Some providers continue charging the full active GPU rate while an instance is running, even when it is not processing requests. Others offer hibernation or paused states with different billing conditions.
Always review the provider's billing policy before estimating costs.
5. Can GPU hibernation reduce monthly hosting costs?#
Yes. GPU hibernation can reduce active compute expenses by pausing GPU resources during periods when they are not required.
However, standby charges, startup behavior, and persistent resource billing may vary by provider.
6. Which GPU is best for a low-budget AI application?#
The best GPU depends on the application's model size, memory requirements, and processing needs.
An entry-level GPU may be sufficient for lightweight inference, while larger models may require more memory and processing power.
Test your application before choosing a long-term configuration.
7. Does GPU hosting include storage and bandwidth?#
Not necessarily. Some hosting plans include certain supporting resources, while others charge separately for storage, networking, or data transfer.
Review the complete pricing information to understand which services are included in your selected plan.
8. How can I predict GPU costs before deploying an AI model?#
Estimate your model's GPU requirements, calculate expected active hours, multiply those hours by the selected GPU's hourly rate, and include additional infrastructure expenses.
You should also account for testing, development, idle periods, and future traffic increases.
Conclusion: Estimate Your GPU Costs Before You Deploy#
Estimating your monthly GPU bill before deployment is an important part of building a sustainable AI application.
Your total computing expense depends on several factors, including GPU hardware, memory requirements, active usage hours, application traffic, idle time, and supporting infrastructure.
Start by understanding your workload, selecting an appropriate GPU, and calculating expected monthly usage. Then account for additional resources and identify opportunities to reduce unnecessary computing expenses.
For applications that do not require continuous GPU processing, hibernation can be an effective way to reduce idle compute costs. For growing applications, flexible GPU configurations can help you scale resources as requirements change.
With hourly pricing, multiple GPU configurations, automated provisioning, and on-demand hibernation, Antryk GPU Application Service gives developers useful tools for planning and managing GPU-powered deployments.
Before launching your next AI or machine learning application, calculate your expected monthly usage and compare the available configurations.
Explore Antryk GPU Application Service pricing:
https://www.antryk.com/pricing/gpu-application-service
Choose the GPU that matches your workload, estimate your computing expenses, and deploy with a clearer understanding of your infrastructure budget.